Sibuna: Architecture, Algorithms, and Empirical Foundations of Work-Bound Web Defense
Vikrant Rathore, with assistance from Ronak Rathore and Kanak Rathore. Insan AI. Whitepaper, November 2026, for Sibuna 1.0.0-beta.3.
Four figures of Sibuna on an AMD Ryzen 9 5950X, 15 October 2026 (benchmarks/results/primitives-latest.md and product-latest.md; the evaluation section gives the method):
- 6.2 ns: a GCRA rate check on a hashed client, 16 shards.
- 55.7 ns: the bot matcher, Aho-Corasick over 40 signatures.
- 22.3 us: verification of a proof of sequential work, depth 13 with 16 openings.
- 16 MiB: peak daemon resident memory under
wrkload, on four CPUs.
Prologue: The Economics of a Request
Every request that reaches a server makes a claim on its attention. A method, a path and some headers do not establish that serving the request is worthwhile. A defense therefore places a decision between the request and the origin: admit it, refuse it, or ask the sender to do verifiable work first. This paper follows that decision from its mathematics to the bytes in memory, in Sibuna.
The voice boxes in this paper are our own words, written in the spirit of Richard Feynman, Donald Knuth and Leslie Lamport, whose way of explaining things we try to follow. They are not quotations, except where a box names its source.
An automated sender pays very little for each request it emits. When a request reaches a conventional firewall, the defender may complete a TLS handshake, allocate memory to copy and split the request, run a list of regular expressions over it, and make a network round trip to a shared store to update a counter. We do not attach a universal ratio to this asymmetry, because none exists: it depends on the origin, the cache and the attack. A simple model makes the decision visible instead. Let \(c_o\) be the origin’s work per admitted request, \(c_g\) the gate’s work per request, and \(a\) the fraction of requests the gate admits. The gate pays for itself only when
that is, when the work it saves the origin exceeds its own cost [1]. Two consequences follow. The gate’s own cost \(c_g\) must be small and bounded whatever the input, and the decision to admit must be expensive for the sender rather than for the server.
Sibuna reverses the asymmetry by conditioning admission on a proof of work. To earn a session, a browser finds a nonce whose SHA-256 digest has \(b\) leading zero bits, or computes a proof of sequential work. The expected search is \(2^b\) hash trials, 65,536 at \(b = 16\); the server checks one candidate. The server’s check is also stateless: issuing a challenge writes nothing, and only a solution that was paid for occupies memory.
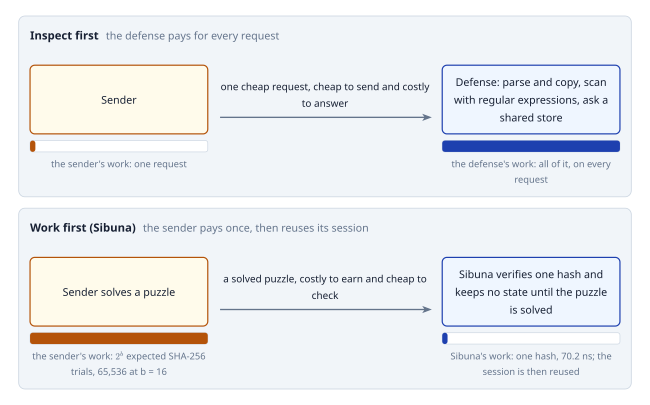
benchmarks/results/primitives-latest.md).¶A proof of work does not establish humanity, identity or intent. A sender can rent computers, share a session within its lifetime, or spread work across machines. The puzzle changes the price of admission; policy and inspection still decide what an admitted request may do.
Design Overview: Three Decisions in One Pass
Sibuna keeps admission, inspection and reputation as three separate decisions, and it takes them in one pass over a request, in one process, before the origin does any work. It offers them as two product surfaces. Gate provides proof-of-work admission with rules, CIDR reputation and local flood controls. Shield, the default, adds bounded inspection of the request payload. Either surface runs as a reverse proxy in front of an origin or as a forward-auth endpoint that an ingress such as Caddy or Nginx consults. Persistent storage of policy, reputation and incident history is an option for either: local to one node, or shared by a cluster [2].
| Capability | Gate (--gate) |
Shield (--shield, default) |
|---|---|---|
| Admission | Hashcash or sequential-work browser challenge; a session token bound to the client and to the work it paid | Same |
| Policy | Declarative rules (path, User-Agent, headers, IPv4 and IPv6 CIDR, a JA4 TLS fingerprint from a trusted ingress) with ALLOW, DENY, CHALLENGE and WEIGH; bot signatures; reputation | Same |
| Flood controls | GCRA rate limits, honeypot, temporary bans | Same |
| Payload inspection | Disabled | SQL injection, cross-site scripting, command injection and path traversal, over the first 8 KiB of the body |
| Optional state | Policy and reputation in SQLite, or shared through PostgreSQL | Also incident forensics: full-text search and campaign clustering |
The Design Choices
Most of the ideas below come from the research literature or from earlier systems, and the book’s Part II traces their lineage. What we have tried to do is to combine them in one bounded request path, to keep each step cheap, and to measure the result honestly. We list the choices with the reason for each.
- Challenges that cost the server nothing to issue. A challenge is a self-authenticating record sealed with a keyed hash, so issuing one writes no state; only a solution that was paid for occupies memory, and it leaves when the challenge expires (Algorithms and Their Guarantees).
- Two tiers of work, chosen per rule. Next to Hashcash, Sibuna offers the Cohen-Pietrzak proof of sequential work, whose soundness has been proved even against quantum provers, and whose proof verifies in microseconds. A checkout route may demand 20 work bits of sequential work while a blog demands 16 bits of Hashcash (Proofs of Work: Parallel Search and Sequential Work).
- Sessions that remember the work paid. A session token records the mechanism and the work bits its holder solved. It admits only routes that demand no more, so a cheap session cannot open an expensive route.
- Symmetric tokens. Sessions are sealed with keyed BLAKE3, which verifies in 155.8 ns, about 260 times less work than an Ed25519 signature, and against which quantum search gives only a quadratic speedup.
- Inspection that a session cannot bypass. Admission and inspection run in the same pass, and a valid session satisfies only a challenge: a request with a session and
q=' OR 1=1--is still refused. - Linear-time, structure-aware inspection. One byte-class scan, one automaton pass and small structural tokenizers decide in time linear in the input, without regular expressions that could backtrack.
- Bounded state with keyed placement. Every table has a fixed capacity and a stated behaviour when it is full, and keys are placed by a keyed hash, so an attacker cannot aim collisions at a victim (Keyed Hashing and the Security Review).
- No allocation per request, and policy updates without pauses. A connection serves every decision from one fixed buffer, and a new policy engine is published without any request or writer waiting (Mechanical Sympathy: Zero Allocation and Bounded State).
- Difficulty that follows the load. Above a baseline of 50 verified solutions per second, each doubling of the rate adds one work bit, up to six, so a flood pays exponentially more while quiet traffic keeps the base cost.
- Campaigns from incidents. Denied requests are recorded with a small embedding, and similar incidents are grouped into campaigns that an operator can investigate from the console.
Mechanical Sympathy: Zero Allocation and Bounded State
The Zero-Allocation Invariant
Every dynamic allocation on a request path is a lever for denial of service: fragmentation over days, contention on the allocator’s locks, and amplification by requests crafted to allocate. Sibuna’s rule is that classification, verification and the proxy hand-off run without heap allocation. A connection owns a 64 KiB read buffer and a 16 KiB write buffer for the life of its socket, and a 40 KiB proxy workspace allocated once when the connection starts. Everything else is a slice into them: the parser locates the method, path, query, headers and cookies of a request inside the read buffer and copies none of them [3]. The implementation’s type system enforces that a parsed request cannot outlive the bytes it describes, so the buffer cannot be refilled while a request still reads it.
The rule is a contract of the request path, not a claim about the whole process. Thread creation, startup and storage allocate. The contract is checked by tests that count allocations: the daemon’s steady-state test counts its allocations, and the proxy’s finds none over 500 proxied keep-alive requests [4].
Bounded Threads, Reused
Each accepted connection is served on a thread of its own, so a slow client delays only itself, and the request path stays synchronous. We considered an event loop and kept the thread model: the speed of the request path comes from a zero-copy parser, a fixed per-connection buffer and allocation-free decisions, none of which an event loop improves [5]. The number of connection threads is bounded by --max-connections (1,024 by default); beyond it the accept loop answers 503 without spawning anything. One socket peer address may hold at most 64 connections by default, and an IPv6 peer is counted with its /64 network.
Threads come from a fixed table of joinable slots. A finished thread keeps its stack until it is joined, so a new task joins and takes the lowest finished slot rather than advancing a cursor; resident memory then follows the connections open, not the connections served. A thread that finishes its connection parks and takes the next one. The section What the Measurement Changed tells how a measurement taught us to add that last rule.
The Request Pipeline
A request passes the checks below in a fixed order. The cheap checks come first, and each decision that ends the request does so before any more expensive stage runs.
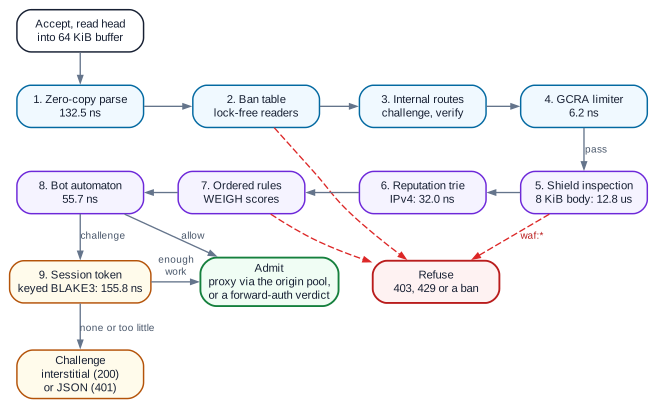
benchmarks/results/primitives-latest.md). Stages run in the numbered order; dashed arrows show early refusals (the GCRA limiter and the reputation trie refuse in the same way). The whole classification of a browser request takes 75.9 ns in the Gate profile and 790.8 ns in the Shield profile.¶A valid session satisfies a challenge; it never overrides a denial or a WAF finding. The proxy, in turn, reads the origin’s response head, classifies its framing (no body, a length, chunked coding, or until close), relays the body exactly, and returns origin sockets left at a clean boundary to a striped pool of 256, so a proxied client connection stays open and the origin is not reconnected for every request.
Publishing Policy Without Stopping Requests
The policy engine is rebuilt off the request path when policies change, and requests must never see a half-built engine. The storage thread builds a complete engine and publishes it, reference counted, in a slot with a generation counter. Each connection keeps a cache: it loads the generation with one acquire load, and it takes a new reference only after a publication. An old engine is freed when the last cache that holds it lets go, and no writer ever waits for readers to drain. Under contention the cached read is more than 400 times cheaper than taking a read-write lock. The engine itself holds about 200 KiB of compact tables (209,052 bytes), with capacity for 128 rules and 8,192 trie nodes.
| Reader | 1 thread | 16 threads |
|---|---|---|
| Read-write lock, read guard only | 4.2 ns | 752 ns |
| Read-write lock and a new reference | 7.6 ns | 833 ns |
| Generation check with a cached reference | 0.8 ns | 1.8 ns |
Locks in Shards
The tables that connection threads share (the spent set, the limiter, the ban table) are split into 16 shards by a hash of the key, and each shard sits on a cache line of its own. Their critical sections are tens of instructions long, so we measured a spin lock against an adaptive mutex, which spins briefly and then sleeps. A spin lock saves about a nanosecond when nobody contends, but an edge server runs more threads than CPUs, and a spin lock whose holder is preempted makes every waiter burn its time slice. The mutex won under contention, so we kept it.
| Workload | Adaptive mutex | Spin lock |
|---|---|---|
| Spent set, 16 threads | 10.8 | 8.6 |
| Spent set, 64 threads | 11.2 | 6.9 |
| GCRA on six hot addresses, 16 threads | 44.9 | 19.3 |
| GCRA on six hot addresses, 64 threads | 37.4 | 6.5 |
Algorithms and Their Guarantees
Each primitive on the request path has a statement of what it costs and what it guarantees. We give three of them as theorems, with the argument in brief; SID 0006 and Parts III to VI of the Sibuna book give the full proofs, the definitions and the references.
The Semantic Firewall
Shield inspects the path, the query, the User-Agent, the headers that are not structural, and the first 8 KiB of the body. Its first version taught us a lesson. It matched a flat list of substrings against every header, the list contained /*, and every browser sends Accept: text/html,...,*/*;q=0.8. Every real browser was classified as SQL injection. Since then a detector may fire only on structure, and a test passes a complete Chrome request through the engine and requires it to come out clean [9].
Inspection has four stages, each linear in the field.
- A byte-class pre-scan. One pass with a 256-entry table records which classes of byte occur: quotes,
=,<, shell separators,%, NUL and the triggers of canonicalisation. Every later detector consults these classes instead of rescanning, so a field without a quote or an equals sign never enters the SQL tokenizer. - A tagged signature automaton. All strong signatures of every category live in one automaton (Theorem 1). A hit is a terminal denial named
waf:sqli,waf:xss,waf:path-traversalorwaf:rce. - Structural tokenizers. The SQL tokenizer looks up each short word in a keyword table and checks
literal = literaltautologies afterorandand; otherwise a quote is mandatory and the evidence must reach a small score. The phrase “it’s a group order from the shop” scores 3 and passes. Cross-site scripting requires a tag that can host script together with an event-handler attribute in attribute position, and command injection requires a separator followed by a command name that is not an assignment, soa=1&id=5is a parameter, not a command. - Canonicalisation. A field with percent escapes, comment openers, JSON or HTML escapes, or collapsible white space is decoded and inspected again, so
1%27/**/UnIoN/**/SeLeCtand%252e%252e/collapse onto the raw signatures.
An 8 KiB body scans in 12,784.3 ns, about 1.56 ns per byte. An operator may audit a category rather than enforce it, so that its findings are logged but not acted on. A field must then be judged per category, so that an audited finding cannot hide an enforced one. Rather than scanning the field once per category, Sibuna scans it once for the set of categories whose signatures occur, and then searches only the wanted categories among them; the same 8 KiB body with SQL injection audited takes 15,485.4 ns [10]. Shield remains a bounded heuristic inspector, not a full SQL or HTML parser, and bytes beyond the inspection bound are not inspected.
TLS Fingerprints From the Ingress
A User-Agent is a string that any client may write as it likes. A JA4 fingerprint is harder to forge. It summarises how a client opens a TLS connection: protocol, version, cipher suites, extensions and the first ALPN value. The client’s TLS library fixes these before the first HTTP byte is sent. Only the component that terminates TLS sees the handshake, so only it can compute JA4. Sibuna terminates no inbound TLS, so it does not compute JA4. It reads the fingerprint that a trusted ingress computed and forwarded in a request header, named with --ja4-header [11].
- Trust. The header is read only when forwarded headers are trusted, by the decision that governs
X-Forwarded-For. From an untrusted peer it is ignored, and in reverse-proxy mode every copy of it is removed before the request reaches the origin. - Validation. A value is accepted only in the 36-byte JA4 form, and only when exactly one field of that name is present. A malformed or repeated value is treated as absent and counted.
- Policy. A rule matches a whole fingerprint, or a prefix followed by
*; a request without a fingerprint never matches such a rule. Matching is a byte comparison, and the warm request path still makes no heap allocation. - Records. Incidents store the fingerprint of their request, and the console shows it in the incident evidence and filters events by it. Bans and reputation stay keyed by address, because many legitimate clients share one TLS library.
Keyed Hashing and the Security Review
An adversarial review of the request path in October 2026 found weaknesses in mechanisms we had considered settled. We fixed each one and recorded the fix in the design record of the mechanism [12].
- Predictable table placement. The limiter and the ban table placed keys with a hash under seeds written in the source, so anyone could compute addresses that share a victim’s probe window. Placement now uses SipHash-1-3 under a key drawn from operating-system randomness, and each table derives its own key. The daemon hashes the client once per request (8.7 ns) and passes the hash to every table; the store path of a request fell from 43 to 26 ns.
- Ban eviction. A ban in effect is never evicted. When every slot a key may take holds a live ban, the new ban is refused and counted, so a banned client cannot evict its own ban.
- Forwarded identity. The leftmost
X-Forwarded-Forentry can be written by the client. Sibuna takes the entry--trusted-hopspositions from the right, the one the nearest trusted proxy appended. - Cookie tossing. A request may carry several values of the session cookie; the daemon tries up to eight, so a cookie planted by a sibling domain cannot keep a visitor in a challenge loop.
- Spent-set capacity. A table of 65,536 tags was exhausted by about 220 verified solutions per second within a five-minute challenge lifetime, after which honest solutions were refused. The capacity is now configurable, 1,048,576 tags (24 MiB) by default.
- Adaptive difficulty. The controller that raises the work under load now counts verified solutions instead of issued challenges, which cost a flooder nothing.
Keyed placement has a price, and we pay it once per request rather than once per table. A limiter check that hashes raw client bytes itself takes 12.8 ns; the check on a hashed client, the path the daemon uses, takes 6.2 ns. Because the limiter and the spent set are allocated zeroed, idle tables are not resident, so their configured capacity costs no memory until it is used.
Proofs of Work: Parallel Search and Sequential Work
The Hashcash Tier
The first tier is Hashcash at bit granularity. For a challenge string \(C\) and difficulty \(b\), the client finds a nonce \(N\) such that \(\text{SHA-256}(C \parallel \texttt{":"} \parallel \mathrm{dec}(N))\) has \(b\) leading zero bits. The decimal rendering of the nonce keeps the wire format identical between the WebAssembly solver, the JavaScript fallback and the native verifier. For ideal digests the number of trials \(K\) is geometric with \(p = 2^{-b}\):
Search has two limits. Its variance is large, so one slow solve is not a broken worker. And independent trials run in parallel, so a sender with more cores finishes sooner, even though the expected total work is the same [13].
The Sequential-Work Tier
The second tier follows the proof of sequential work of Cohen and Pietrzak (EUROCRYPT 2018). Its labels form a complete binary tree of depth \(n\). An internal node hashes its two children. A leaf hashes the left siblings of its ancestors wherever its root path turned right. Those left-sibling edges make the computation sequential: a leaf cannot be labelled until every subtree to its left is complete, so the root label depends on all \(2^{n+1} - 1\) labels in order. After computing the root \(\varphi\), the prover derives \(t\) leaves by Fiat-Shamir and, for each, sends the leaf label and the \(n\) sibling labels along its path. The verifier recomputes each opened leaf and hashes up to \(\varphi\), at a cost of \(O(tn)\) label computations in a fixed workspace.
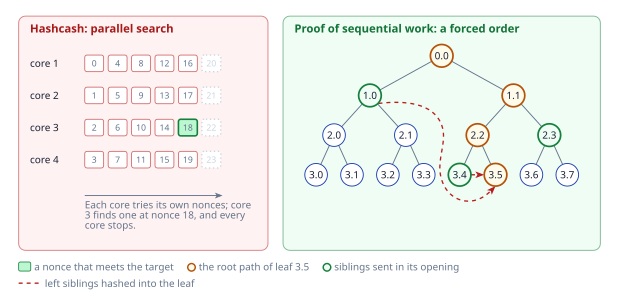
The parameters are chosen so that the numbers stay small. Work bits map to depth by \(n = b - 3\), clamped to \([4, 24]\). A proof has \(32(1 + t(n+1))\) bytes, which at depth 13 with 16 openings is \(32(1 + 16 \times 14) = 7200\) bytes. The prover keeps only the top levels of the tree and recomputes the subtree it must open, so its whole workspace, the proof included, stays under 100 KB; a browser tab and the native tests use the same prover [14]. Blocki, Lee and Zhou (ITC 2021) proved the construction sound against quantum provers in the quantum random-oracle model.
We should be careful about what this establishes. The security results hold under the random-oracle assumptions of the papers, for the constructions and bounds they state. They are not an independent audit of our concrete SHA-256 protocol, its parameter mapping or its browser timing. The elementary sampling bound \((1-\alpha)^t\), the chance that \(t\) independent openings all miss a fixed bad fraction \(\alpha\), explains why more openings help; it is not by itself a proof against a prover who grinds many roots. We make no unconditional claim that cheating is never cheaper.
The Round Trip and the Session
A navigation without a valid session receives the interstitial page, which carries a requirement ticket: the challenge this decision demands (algorithm, work bits, openings) and the rule’s hash, sealed for this client and valid for one challenge lifetime. The page fetches its challenge with the ticket, so the work is fixed by the decision that demanded it. A Web Worker solves the challenge with the WebAssembly prover, or with a JavaScript fallback where WebAssembly is unavailable, and posts the answer. On success the server sets a session cookie of 75 characters, bound by a keyed fingerprint to the client’s address and User-Agent, and the page reloads. The prover in the browser is compiled from the same source as the server’s verifier, so the two cannot drift apart [15].
What Verification Costs
Both tiers are bound by SHA-256, and Sibuna selects the processor’s SHA instructions at run time where they exist, so one binary is fast on every machine that has them. Hashcash verification at 16 bits takes 70.2 ns, and verifying a depth-13 proof with 16 openings takes 22,272.4 ns. The browser prover is a WebAssembly module of 14,744 bytes. In the end-to-end browser check, headless Chromium solved the interstitial’s challenge in 29 to 34 ms with WebAssembly and in 84 to 91 ms with the JavaScript fallback [16]. The primitive suite measures verification only; a native timing does not stand for a browser’s solve time.
Sessions use a symmetric token. The verifier is the issuer, or a cluster that shares one seed, so a keyed pseudorandom function supplies exactly the authentication needed. A keyed-BLAKE3 token verifies in 155.8 ns and an Ed25519 token in 40,587.5 ns, so one signature verification costs about as much as 260 MAC verifications. There is a second reason for the choice: Shor’s algorithm breaks the discrete logarithms beneath Ed25519, while against a keyed hash quantum search gives at most a quadratic speedup. Ed25519 remains an option for deployments that need verifiers who cannot mint tokens.
Shared State Without a Consensus Protocol of Our Own
Why SQL, and Why Not a Consensus Protocol of Our Own
Sibuna stores little: a few hundred policy rows, a reputation table, and forensic incidents that operators also export to other systems. That state does not need a bespoke replicated engine. It needs a reliable SQL store, local for one node and shared for many. A single node therefore keeps its state in an embedded SQLite file in its data directory, in WAL mode, and a cluster points every node at one PostgreSQL database [17].
We chose not to run a consensus protocol inside the firewall. A consensus engine is a large system to own beside a firewall, with its own formats and its own failure modes, and it adds work to shutdown and to every upgrade. The availability and replication of a cluster’s state are instead PostgreSQL’s concern, served by its streaming replication and failover tools or by a managed service. We think this is the humbler choice: PostgreSQL’s replication has been exercised by far more deployments than ours could be, and Sibuna’s write rate (batched incidents and rare policy changes) is small enough that one primary is not a bottleneck.
Storage also stays optional. Without --data-dir or --database-url the daemon is an in-memory firewall whose policies come from a file.
One Storage Thread
One storage thread owns the database connections; nothing else touches SQL. Request threads never wait on it. They push incident records into a bounded ring of 512 slots, which drops and counts a record when it is full, and they read the published engine. Every 500 ms by default the storage thread runs one tick: it writes up to 32 queued incidents in one transaction, reads the policy revision and, when it changed, rebuilds the engine and publishes it. A rebuild reads the revision before and after loading; if a writer committed in between, the candidate is discarded and the old engine stays live. Operators may write the policy tables directly: triggers advance the revision in the writer’s transaction, and under PostgreSQL a NOTIFY lets nodes tick at once, while polling remains the guarantee [18].
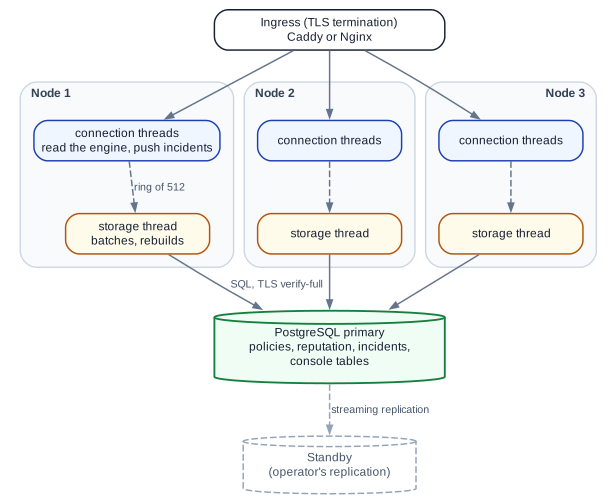
Each node of a cluster has a distinct --cluster-node identifier between 1 and 8,388,607. Challenge keys are bound to the issuing node, so a solution must return to the node that issued its challenge, while session tokens and requirement tickets are valid on every node that shares the seed. Incident identifiers carry the node in their top bits, and each node keeps a durable receipt advanced in the same transaction as its batch, so a batch replayed after an ambiguous failure writes nothing twice.
A Typed Schema
The schema states in SQL what the program’s types state, so the database refuses a row the storage layer could not represent. SQLite tables are STRICT; an enumerated column has a CHECK that lists exactly the names the program writes; a bounded integer has a range check; and a column is NOT NULL exactly when the value is never absent. Every statement binds its values as parameters, so no SQL is built by quoting. The console’s storage follows the same rules: one baseline migration of 33 typed tables and no triggers. Each invariant of the console, such as “every change to a token writes an audit row”, is enforced by exactly one function that runs its statements in one transaction, on SQLite and PostgreSQL alike [19].
Connections to PostgreSQL are protected as the URL says, with libpq’s sslmode and sslrootcert, when the daemon is built with the postgres-tls feature. A build without that feature refuses require, verify-ca and verify-full at startup; it never falls back to plaintext. Production clusters use sslmode=verify-full.
Incidents that look alike are grouped into campaigns. Each incident carries a 64-dimension embedding stored as 256 bytes. The storage thread keeps the most recent 16,384 embeddings of all nodes in memory (4 MiB) and assigns an incident to the campaign of its nearest neighbour when the cosine distance is at most 0.35. Clustering against older incidents is a deliberate omission: campaigns are recent by nature, and the bound keeps memory and work fixed.
What This Design Does Not Do
We should be plain about the limits of this choice. Sibuna contains no consensus protocol of its own, and a cluster’s consistency is PostgreSQL’s: a node that loses the database keeps its last policy until it reconnects. A session minted on one node is accepted by every node, and a solution spent on one node is refused when replayed to another, because the nodes share one seed and challenge keys are bound to the issuing node; neither property needs the database. SID 0011 is committed: a functional test with three nodes on one PostgreSQL database shows that a policy inserted on one node is enforced by all three within one tick, that a honeypot ban on one node reaches the others, and that incident identifiers never collide. No harness yet drives several nodes on one PostgreSQL database under load, so this paper reports no cluster measurements. The release executables are built without PostgreSQL support; a cluster builds Sibuna from source with the postgres-tls feature [20].
The Console
Sibuna includes an opt-in management console: authenticated dashboards with live traffic, an investigation path from a denial to its recorded evidence, policy editing, address groups, country enrichment from open GeoIP data, users with Argon2id passwords and a TOTP second factor, an audit trail, webhooks, and the management of a cluster. It is compiled into the same binary, and its interface runs in the browser as a WebAssembly module [21].
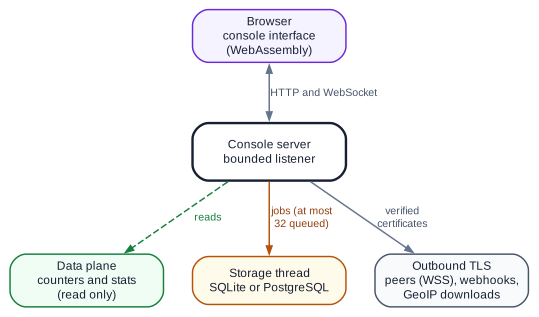
The console’s defining constraint is isolation from the request path. It may read the data plane’s counters and its database and write the database, but it never enters a request thread, never allocates on one, and never holds a lock a connection thread needs. Its listener admits at most 96 connections, of which 16 are reserved for HTTP, 64 may be browser streams and 16 peer streams. In 1.0.0-beta.3 the complete interface module measures 724,330 bytes (272,568 bytes compressed with gzip). That is below the ceiling of 768 KiB, which the build enforces, and above the review threshold of 640 KiB, which SID 0007 records for review [22].
The console makes outbound TLS connections for long-lived peer streams, webhooks and GeoIP downloads. Certificates are verified against the system roots or an operator’s CA file, host-name verification cannot be disabled, plain HTTP is allowed only to literal loopback addresses, and a certificate error never falls back to plaintext. Sibuna still terminates no inbound TLS; that remains the job of the ingress.
SID 0007 sets the console’s performance target: enabling it may cost at most 1% of data-plane throughput and at most 10% of p99 latency. One measurement exists: with the console compiled in but disabled, with storage only, or enabled and idle, the 16 whole-product workloads stayed within about 1% of a daemon built without it, which is within noise. The formal gate, with eight active dashboards under load, has not been run, so we do not claim that the target is met. A functional run with eight live dashboards passed.
| Measure | Value |
|---|---|
| Data-plane requests | 6,000 in 30.0 s (200 per second, one connection per request) |
| Answered | 6,000: 200 x 1,200, 401 x 3,000, 403 x 600, 404 x 600, 500 x 600 |
| Errors (no reply) | 0 |
| Latency p50 / p90 / p99 / max | 246 / 311 / 373 / 552 us (connect included) |
| Daemon resident memory at start, with 8 dashboards, after the traffic | 36,152 KiB; 38,028 KiB; 41,496 KiB |
| Dashboards | 3 administrator sessions and 5 wall displays; each received 134 to 139 stats deltas and ended with the same totals, with no exception, console error or Content-Security-Policy violation |
Empirical Evaluation
Method
Three harnesses, run through cargo xtask bench, measure Sibuna. The primitive suite times the operations of the request path in seven timed batches after an untimed warm-up, rebuilds mutable state outside the timer, and reports the median batch per operation with the fastest and slowest batch beside it. The whole-product harness drives the daemon with wrk (2 threads, 64 connections, 5 seconds, 3 repetitions) in forward-auth and reverse-proxy modes, on the Gate and Shield surfaces, over four workloads: admitted (a valid session), challenged (no session), allowed_static (/robots.txt) and attack (a session plus q=' OR 1=1--, which only Shield refuses). The latency harness uses an open-loop generator that sends at a fixed rate whatever the daemon does, and times each request from when it was due, so that queueing in the daemon is charged to the daemon [23].
The runs were recorded on 15 October 2026 on one host: an AMD Ryzen 9 5950X (16 cores, 32 threads) running Linux 7.0.0-28. The daemon ran on CPUs 0 to 3 with four workers, the load generator and a stub origin on CPUs 8 to 15 (the other CCD), and the primitive suite on CPU 4. The daemon was the default release build, with SQLite and the console compiled in, and ran in memory, without storage.
Primitive Latencies
| Subsystem | Workload | Median | Min-max |
|---|---|---|---|
| Proof of work | Hashcash verify, 16 bits | 70.2 | 69.9-71.0 |
| Proof of work | PoSW verify, depth 13, 16 openings | 22,272.4 | 22,257.0-22,316.4 |
| Bot matcher | Aho-Corasick, 40 signatures | 55.7 | 55.3-57.2 |
| Bot matcher | Sequential substring search, 40 signatures (for reference) | 763.0 | 762.2-763.5 |
| IP classifier | IPv4 CIDR lookup | 32.0 | 31.8-32.2 |
| IP classifier | IPv6 CIDR lookup | 79.3 | 78.5-79.6 |
| Token | Keyed BLAKE3 session token | 155.8 | 155.3-156.4 |
| Token | Ed25519 session token | 40,587.5 | 40,544.6-40,631.1 |
| Spent set | Robin Hood spend and look up | 21.0 | 20.8-21.3 |
| Rate limiter | GCRA, hashed client | 6.2 | 6.1-6.3 |
| Rate limiter | GCRA, four rule scopes, hashed client | 6.3 | 6.2-6.4 |
| Rate limiter | GCRA, client as bytes (keyed hash included) | 12.8 | 12.7-12.8 |
| Rate limiter | GCRA, four rule scopes, client as bytes | 13.1 | 13.0-13.2 |
| HTTP parser | Zero-copy request and cookie | 132.5 | 132.3-133.2 |
| Policy engine | Full classification, Shield profile | 790.8 | 787.2-793.1 |
| Policy engine | Classification, Gate profile | 75.9 | 75.6-76.1 |
| WAF | 8 KiB body, semantic scan | 12,784.3 | 12,771.5-12,809.2 |
| WAF | 8 KiB body, SQL injection audited | 15,485.4 | 15,460.9-15,530.1 |
The spreads are narrow: no batch of any row lies more than 4.2% from its row’s median [24]. The daemon uses the rows on a hashed client, because it hashes the client once per request; the rows that pass raw bytes include that keyed hash on every check. Timers surround whole batches, never single operations, so the table reports no per-operation percentiles.
Whole Products
| Mode | Surface | Workload (status) | req/s | p50 | p99 | CPU | Peak KiB |
|---|---|---|---|---|---|---|---|
| forward auth | Gate | admitted (200) |
211,345 | 151 | 305 | 11.84 | 15,912 |
| forward auth | Gate | challenged (401) |
198,315 | 160 | 326 | 13.15 | 16,176 |
| forward auth | Gate | allowed_static (200) |
211,053 | 152 | 305 | 11.73 | 16,176 |
| forward auth | Gate | attack (200) |
211,618 | 151 | 305 | 11.84 | 16,176 |
| forward auth | Shield | admitted (200) |
208,101 | 152 | 308 | 12.87 | 15,928 |
| forward auth | Shield | challenged (401) |
197,532 | 161 | 327 | 13.77 | 16,192 |
| forward auth | Shield | allowed_static (200) |
211,636 | 151 | 305 | 11.78 | 16,192 |
| forward auth | Shield | attack (403) |
210,549 | 152 | 307 | 12.32 | 16,192 |
| reverse proxy | Gate | admitted (200) |
142,498 | 427 | 768 | 27.68 | 15,896 |
| reverse proxy | Gate | challenged (200) |
199,465 | 160 | 324 | 12.98 | 16,160 |
| reverse proxy | Gate | allowed_static (200) |
147,303 | 411 | 759 | 26.88 | 16,324 |
| reverse proxy | Gate | attack (200) |
143,900 | 422 | 745 | 27.67 | 16,348 |
| reverse proxy | Shield | admitted (200) |
138,965 | 438 | 857 | 28.57 | 16,064 |
| reverse proxy | Shield | challenged (200) |
195,188 | 162 | 328 | 13.73 | 16,328 |
| reverse proxy | Shield | allowed_static (200) |
145,673 | 415 | 746 | 27.27 | 16,328 |
| reverse proxy | Shield | attack (403) |
209,507 | 151 | 306 | 12.17 | 16,328 |
In forward-auth mode the ingress asks Sibuna whether to admit a request, and there is no origin; every workload lies between 197,532 and 211,636 requests per second with a p99 of 305 to 327 us. The four daemon CPUs are not saturated there (between 2.47 and 2.72 of them are busy), which points to the load generator as the ceiling. In reverse-proxy mode the admitted and static rows include the stub origin and one more loopback hop, and the daemon’s CPUs are saturated (3.95 to 3.98 of four busy); requests that Sibuna answers itself (challenges, and Shield’s refusal of the attack) still run at about 195,000 to 210,000 per second. Peak resident memory stays between 15,896 and 16,348 KiB in every workload [25].
A few answers in about two million in three reverse-proxy rows were 503: wrk reconnected before a closing connection had given back its place under the per-address connection limit. The daemon now gives the place back before it writes the closing response; these files predate that fix.
| Measure | Value |
|---|---|
| Daemon binary, default build with SQLite and the console | 49,113,856 bytes |
| Idle resident memory, product runs | 5,592 to 5,788 KiB |
| Peak resident memory during a workload | 15,896 to 16,348 KiB |
| Resident memory after the workloads | 16,176 to 16,348 KiB |
| Policy engine tables | 209,052 bytes |
| Bot signature table | 42,244 bytes |
| WAF signature table | 164,908 bytes |
| Browser prover (WebAssembly) | 14,744 bytes |
A later change to the release profile drops the bundled SQLite’s debug information, about 13 MB of the 49 MB by the note in the build manifest; the result files have not been regenerated since, so we quote the measured size [26].
Latency at Equal Offered Load
wrk keeps 64 requests in flight, so the request rate depends on the daemon, and wrk’s percentiles leave out the requests it did not send while it waited. The open-loop harness fixes the offered rate instead and charges every delay to the daemon, which is what a visitor experiences.
| Mode | Offered req/s | Achieved req/s | p50 | p90 | p99 | p99.9 | Errors | CPU us |
|---|---|---|---|---|---|---|---|---|
| forward auth | 10,000 | 10,000 | 30 | 32 | 37 | 58 | 0 | 16.92 |
| forward auth | 25,000 | 25,000 | 28 | 31 | 34 | 45 | 0 | 15.83 |
| forward auth | 50,000 | 50,000 | 25 | 27 | 30 | 40 | 0 | 13.83 |
| forward auth | 100,000 | 99,998 | 24 | 26 | 41 | 62 | 0 | 13.48 |
| forward auth | 150,000 | 149,996 | 25 | 36 | 51 | 74 | 0 | 14.16 |
| reverse proxy | 10,000 | 10,000 | 56 | 61 | 65 | 76 | 0 | 32.25 |
| reverse proxy | 25,000 | 25,000 | 51 | 54 | 58 | 72 | 0 | 28.63 |
| reverse proxy | 50,000 | 50,000 | 47 | 50 | 60 | 74 | 0 | 27.45 |
| reverse proxy | 100,000 | 99,996 | 55 | 75 | 100 | 150 | 0 | 28.42 |
| reverse proxy | 150,000 | 134,344 | 583,934 | 1,544,160 | 1,906,273 | 1,967,134 | 4 | 29.22 |
In forward-auth mode the p99.9 stays below 75 us up to 150,000 requests per second. In reverse-proxy mode, with the origin in the path, the p99 is 100 us and the p99.9 150 us at 100,000 requests per second. At 150,000 requests per second in reverse-proxy mode the daemon is past its capacity: it completes 134,344 requests per second, close to the 138,965 that wrk measured for the same workload, and latency grows to seconds, as an open-loop test should show above capacity. The four errors of that row occurred in the overload [27].
What the Measurement Changed
The latency harness changed the design of the connection threads. In its first runs, with 64 connections each closed by the daemon after 4,096 requests, the 99.9th percentile at 100,000 admitted requests per second was 0.3 to 2 ms, a tail that wrk had not shown. Creating and ending a thread maps and unmaps its signal stack and returns its stack pages, and those changes to the address space stalled the other threads. One experiment settled the diagnosis: a build that never closed connections, and so created no thread during the run, gave 54 to 60 us at the same rate. The fix lets a thread that finishes its connection park and take the next one; a thread parked for 10 seconds ends, so a burst does not leave its stacks resident. After the fix the p99.9 at 100,000 requests per second is 62 us in forward-auth mode and 150 us in reverse-proxy mode [28].
A rare, periodic stall moves the far tail long before it moves p99. At 100,000 requests per second over 64 connections, each connection lasts \(4096 / 1562.5 \approx 2.6\) s, so about 24 threads start and end every second; in a run of one million requests the top 0.1% is only 1,000 requests, and a few delayed requests per thread turnover are enough to fill it. Such a defect needs p99.9 and a timer on every request to be seen.
Key Takeaways
- Classification below a microsecond. In the Gate profile the policy engine classifies a browser request in 75.9 ns; with full inspection in the Shield profile it takes 790.8 ns.
- Symmetric verification. A keyed-BLAKE3 session token verifies in 155.8 ns, against 40,587.5 ns for an Ed25519 token: about 260 times less work for the same integrity within one trust domain.
- A small, steady footprint. About 200,000 forward-auth requests per second on four CPUs, with peak resident memory near 16 MiB in every workload and under 6 MiB at idle.
- Tails need open-loop measurement. The thread-turnover stall was invisible to the closed-loop harness and obvious at p99.9 under an open-loop generator.
Market Comparison: Sibuna and Its Neighbours
We compare Sibuna with the tools an operator is most likely to weigh against it. The facts about the other products were read from their public documentation and release artefacts in September 2026, and the Sibuna book records them with their sources in Part II [31]. Each of these products serves its users well, and each made design choices whose benefits our harness does not measure. We describe the differences in architecture, not a ranking.
| Feature | Sibuna 1.0.0-beta.3 | Anubis 1.27 | SafeLine CE 9 | Cloudflare WAF |
|---|---|---|---|---|
| Runs as | One binary; reverse proxy or forward auth; optional SQLite file or shared PostgreSQL database | One Go binary; reverse proxy or forward auth | Seven Docker containers (tengine, detector, mgt, luigi, fvm, chaos, PostgreSQL) | Hosted network; DNS points at Cloudflare |
| Runtime | Native code, no garbage collector; no third-party dependency when storage is off | Go, garbage collected | C/C++ proxy and detector, Go management, PostgreSQL | Proprietary edge software |
| Licence | LGPL-3.0-or-later | MIT | GPL-3.0 management code; closed detector images | Proprietary service |
| Proof-of-work admission | Hashcash (bit-level) and Cohen-Pietrzak sequential work, chosen per rule | SHA-256 Hashcash in hex nibbles; non-work challenges | JavaScript challenge and CAPTCHA; not work-bound | Managed challenge, JS challenge, Turnstile |
| Challenge state on the server | None until solved; solved tags in a fixed Robin Hood table | Store backend: memory, bbolt, Valkey or S3 | Managed by the stack | Managed by Cloudflare |
| Session token | Keyed BLAKE3, 75 characters, bound to the work paid; Ed25519 optional | JSON Web Token signed with Ed25519; HS512 optional | Cookie issued by the stack | cf_clearance cookie |
| Payload inspection | Shield: tagged automaton plus structural tokenizers, first 8 KiB of body | None | Semantic analysis over OWASP categories | Managed rulesets (Pro and above) |
| TLS fingerprint (JA4) | Rules match a JA4 value that a trusted ingress forwards; not computed by Sibuna | Not documented; policies may reference the HTTP fingerprint JA4H, which Anubis computes | Computed at its own TLS termination; custom rules and a built-in deny list | JA3 and JA4 in custom rules and analytics (Enterprise with Bot Management) |
| Shared state | One PostgreSQL database for policy, reputation and forensics | Shared signing key; shared Valkey store | One stack per host | Global anycast network |
| TLS termination | No (ingress) | No (ingress) | Yes | Yes |
Measured Comparison With Anubis
We measured the official Anubis v1.27.0 release binary beside Sibuna with the harness of Whole Products: the same four workloads, the same four CPUs for every product thread, the same wrk load, matched Hashcash work (8 zero bits for Sibuna, 2 zero hex digits for Anubis), a session obtained by solving each product’s challenge as a browser would, and caddy respond as the origin [29]. Sibuna runs its Shield surface here, so it also inspects every payload, which Anubis does not.
| Mode | Workload | Sibuna req/s | Sibuna p99 | Anubis req/s | Anubis p99 |
|---|---|---|---|---|---|
| forward auth | admitted |
208,635 | 308 | 36,509 | 7,477 |
| forward auth | challenged |
193,087 | 342 | 113,170 | 3,781 |
| forward auth | allowed_static |
212,444 | 304 | 89,904 | 4,547 |
| forward auth | attack |
211,347 (403) | 306 | 36,853 | 7,283 |
| reverse proxy | admitted |
103,298 | 3,321 | 19,398 | 11,062 |
| reverse proxy | challenged |
197,327 | 328 | 28,842 | 9,546 |
| reverse proxy | allowed_static |
106,819 | 3,316 | 28,862 | 30,124 |
| reverse proxy | attack |
210,483 (403) | 306 | 23,399 | 14,124 |
Anubis spends 106 us of CPU per admitted request in forward-auth mode, where Sibuna spends 13; its peak resident memory was about 32 MiB in forward-auth mode and grew to about 600 MiB in reverse-proxy mode, while Sibuna’s stayed near 16 MiB throughout. Behind caddy respond Sibuna’s proxied rows are limited by the origin, which shares the load generator’s CPUs: with the lighter stub origin of Whole Products the same rows reach about 139,000 requests per second.
| Product (token) | Session check | Unauthenticated | Bootstrap | Proof verification | Resident memory |
|---|---|---|---|---|---|
| Sibuna (keyed BLAKE3) | 88,104 | 78,997 | 42,664 | 57,924 | 7.6 MiB |
| Anubis (Ed25519) | 10,951 | 28,619 | 7,893 | 12,668 | 32.6 MiB |
| Anubis (HS512) | 16,976 | 27,785 | 7,952 | 19,261 | 29.1 MiB |
Detailed Architectural Comparison
SafeLine (Chaitin Technology)
SafeLine carries the semantic idea of libinjection into a complete product with a management console, and its vendor reports detection rates of 71.65% (balanced mode) and 76.17% (strict mode) with false-positive rates of 0.07% and 0.22% [32]. These are measurements of detection quality, which Sibuna has not published for its own engine.
- Deployment. The community edition ships as seven Docker containers on a Linux host with at least one CPU core, 1 GB of memory and 5 GB of disk. It terminates TLS itself, which Sibuna does not.
- State. It keeps its attack log in PostgreSQL within the stack, one stack per host.
- Where Sibuna differs. Sibuna is one binary that starts with an optional SQLite file, and a cluster shares one PostgreSQL database that the operator may already run. Its idle resident memory was 5,592 to 5,788 KiB in the product runs. We have not run SafeLine on our host, which had no Docker daemon, so we make no performance comparison.
Anubis and Coraza
The proof-of-work interstitial became common in 2025, when scraper traffic for language-model training made ordinary origins expensive to run, and Anubis is its best-known open implementation. It is a capable, widely deployed Go reverse proxy: it serves a JavaScript puzzle, signs a JSON Web Token with Ed25519, and keeps challenge state in a store. Coraza implements the ModSecurity rule language (SecLang) and runs the OWASP Core Rule Set; it is one way to add rule-based inspection beside such a gate.
- Where the work goes. Anubis and Sibuna Gate both make the client pay before the origin does anything. Sibuna adds a second tier of sequential work, chosen per rule, for routes that deserve a stronger gate, and its sessions remember how much work was paid.
- What the server remembers. Anubis stores challenges; Sibuna issues a self-authenticating record and remembers only solved tags, in a fixed table (Theorem 3). Its default token is symmetric, which is cheaper to verify and leaves a quantum attacker only a quadratic speedup.
- Inspection. Sibuna Shield performs its own structural inspection in the same pass as admission, so one process and one parser serve both roles. It does not run the OWASP Core Rule Set. We evaluated the existing SecLang engines, including bindings to libmodsecurity and Coraza, and admitted none: an inspection engine on an edge server is security-critical code we prefer to own and review. If Sibuna adds compatibility with the Core Rule Set, a design record will specify the subset first [33].
- Measurement. On one host under the same load, Sibuna answered more than five times as many admitted requests in forward-auth mode with a lower p99 and about an eighth of the CPU per request (Measured Comparison With Anubis).
Cloud Edge WAFs (Cloudflare and Others)
Hosted edges place inspection, rate limiting and bot scoring in many points of presence with a global control plane. They absorb volumetric attacks that no single server can, and they need no hardware from the operator. Sibuna’s cluster deployment borrows their shape, a shared policy plane feeding local immutable snapshots, while staying self-hosted.
- Data residency. A hosted WAF terminates the operator’s TLS and sees request payloads on shared infrastructure, which can conflict with data-residency requirements.
- Plans and quotas. Features are tied to plans: Cloudflare’s published quotas allow 5, 20, 100 and 1,000 custom rules and 1, 2, 5 and 100 rate-limiting rules on the Free, Pro, Business and Enterprise plans.
- Where Sibuna differs. Sibuna runs on the operator’s own machines with no per-request fee, and its policy changes reach every node on the next storage tick (500 ms by default). It does not mitigate volumetric network attacks, does not score bots with a trained model, and does not terminate TLS; a deployment that needs those still needs an ingress or an edge network in front of it.
Implementation: Small Crates and Few Dependencies
Sibuna is written in Rust, as a workspace of small crates whose dependencies point one way: reusable libraries, then a core of configuration and diagnostics, then the application libraries, then the daemon and the browser prover. Three engineering choices matter to an operator, so we record them briefly [34].
Few dependencies. We treat every third-party library as a liability: it must be reviewed, updated and trusted. The data plane uses none. Hashing, signatures, base64, JSON, DEFLATE, Aho-Corasick and the HTTP/1.1 parser are small libraries of our own, which other projects may use on their own. A dependency is admitted only when it is mature, self-contained and solves a genuinely large problem, and the reason is written beside it in the build manifest and in a design record. Two have been admitted, each confined to one library: sqlx for SQLite and PostgreSQL storage, which brings about one hundred transitive crates [35], and rustls for the console’s outbound TLS and PostgreSQL’s TLS, thirteen crates at run time, because a TLS client written in-house would be a security-critical project larger than Sibuna’s data plane [36]. A build without storage and the console has no third-party dependency at all.
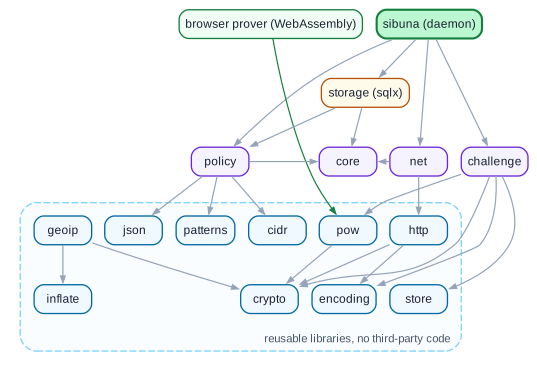
Memory safety. Code that bypasses the compiler’s memory-safety checks is denied by default, and a module that needs it must opt in by name and justify each use in a comment. A few modules do: the paths that use the processor’s SHA instructions, one write that wipes secrets, the declarations of a few C library functions for signal handling, the exports of the two WebAssembly modules, and the ring that carries incidents to the storage thread. The ring is the one place where we kept such code for speed, and only after a measurement: the standard library’s bounded channel cost 20 to 45% more per push with 16 producers [37]. Elsewhere ownership does the work that hand-written memory management would otherwise do: a parsed request cannot outlive its buffer, an engine is freed with its last reader, and a socket cannot be closed while any thread can still reach it.
Discipline and tests. A function body has at most 70 logical lines and a file at most 1,408 lines, enforced by a checker. Library code returns structured errors and never prints, and every error a user sees names its location, shows an excerpt, and gives a hint. The workspace suite of 1.0.0-beta.3 runs about 2,200 tests on SQLite and about 700 more against PostgreSQL; the console’s interface has 298 tests, including golden fixtures; and browser checks drive headless Chromium through the interstitial and through every console page [30].
Limitations and Open Work
We list what this paper does not establish, so that no claim is read more widely than its evidence.
- One measured neighbour. We measured Anubis on one host (Measured Comparison With Anubis). We have measured neither SafeLine nor a hosted WAF.
- No cluster under load. A functional test runs three nodes on one PostgreSQL database (SID 0011, committed), but no harness drives several nodes under load.
- PostgreSQL needs a source build. The release executables have SQLite storage and the console but no PostgreSQL support; a cluster builds Sibuna with the
postgres-tlsfeature. - The console’s isolation gate with eight active dashboards under load has not been run (The Console).
- Loopback only. No measurement covers TLS, a wide-area network or real browsers under load; a deployment should measure its own path.
- Bounded inspection. Shield is a heuristic inspector of the first 8 KiB of a body, not a full SQL or HTML parser, and forward-auth inspection sees only the bytes the ingress sends.
- Protocol scope. Sibuna speaks HTTP/1.0 and HTTP/1.1; it has no HTTP/2 and no inbound TLS termination.
- TLS fingerprints come from the ingress. Sibuna cannot compute JA4 itself. A fingerprint is only as trustworthy as the ingress that writes it, and that ingress must overwrite any copy a client sent. A client can imitate a browser’s handshake with specialised libraries, so JA4 raises the cost of automation; it does not prove identity [11].
- Cryptographic assurance. The sequential-work tier rests on published proofs in the random-oracle model; our concrete protocol has tests against a reference labeller, not an independent cryptographic audit.
- One machine. Every number was taken on one AMD Ryzen 9 5950X. A ranking on this host is not a ranking on another.
Conclusion
Web defense has often grown by accretion: interpreted runtimes, containers, regular-expression rule sets and external stores piled in front of an application. With Sibuna we have tried the opposite direction, guided by a few plain ideas:
- make the sender pay for admission with verifiable work, keep the server’s check cheap and stateless, and let a session remember how much work it paid;
- inspect by structure in linear time, in the same pass as admission, so that no session can bypass inspection;
- respect the machine: one buffer per connection, no allocation on the request path, bounded tables with keyed placement, and threads that are reused rather than recreated; and
- let a mature database own durable shared state, behind one storage thread that the request path never waits on.
On one 16-core machine, these choices let Sibuna serve more than 200,000 admitted requests per second in forward-auth mode on four CPUs, with about 16 MiB of resident memory under that load and a p99.9 of 62 us at 100,000 requests per second. These are the numbers of one host over loopback, and we offer them as evidence that the design holds together, not as a ranking. We removed our own consensus protocol and say so plainly; in return the system is smaller and its data plane has no third-party dependency. Much remains to be measured, and we have tried to say exactly what.
Sources and Reproduction
Every number in this paper comes from a committed result file of the Sibuna repository, from a Sibuna Discussion (SID) record, or from the Sibuna book, and each table or footnote names its source. The result files are written by cargo xtask bench primitives, cargo xtask bench product and cargo xtask bench latency, and benchmarks/results/README.md gives the commands, the CPU sets and the provenance of each file.
benchmarks/results/primitives-latest.md,product-latest.md,latency-latest.mdand their.jsonfiles;console-8-dashboards-2026-10-15.md.- SID 0002 (foundation architecture and its revision notes), SID 0004 (the Shield surface), SID 0006 (mathematical foundations), SID 0007 (the console), SID 0010 (workspace, crates and dependency policy), SID 0011 (storage through sqlx), SID 0012 (console TLS), SID 0013 (console storage) and SID 0014 (JA4 fingerprints from the ingress), in
docs/sid/records/. - The Sibuna book,
docs/book/: Part I (the cost of a request), Part II (prior art), Part III (cryptography), Part IV (the protocol), Part V (zero-allocation engineering), Part VI (automata and the semantic firewall), Part VIII (empirical evaluation) and Part IX (operations). - The primary literature: Back, Hashcash (1997); Cohen and Pietrzak, Simple Proofs of Sequential Work (EUROCRYPT 2018); Blocki, Lee and Zhou, On the Security of Proofs of Sequential Work in a Post-Quantum World (ITC 2021); Aho and Corasick, Efficient String Matching (1975); Celis, Robin Hood Hashing (1986); the ATM Forum’s Generic Cell Rate Algorithm (1996).
Notes